
Define Failure Before Testing an HVAC Predictive Alert
A model can flag an unusual operating pattern without predicting a component failure. Before evaluating a predictive-maintenance offer, define the event it claims to predict, the time window, the equipment population, and the action the service team can take. An impressive accuracy figure is difficult to interpret without those details.
Separate detection, diagnosis, and prediction
Detection identifies a condition or pattern now. Diagnosis interprets its cause. Prediction concerns a future event. One product may provide more than one function, but evidence for one should not be presented as proof of the others.
In an invented example, a system detects a temperature pattern outside its learned range. That may justify qualified investigation. It does not establish that a compressor will fail, which part caused the pattern, or how much useful operating time remains.
Ask the provider to state the output in plain language. Is it a current fault classification, a risk score, an estimated remaining life, or a notification that data is unavailable? The service process should preserve that meaning when displaying the result to staff and customers.
Specify the event and the time horizon
“Failure” might mean an unplanned loss of service, an observed component defect, a fault code, a work order, or a replacement decision. These are not identical. A work order can reflect a customer request or planned maintenance rather than a physical failure.
Define who establishes the event and which evidence supports it. For a particular model, the team might evaluate a clearly defined event within a stated future period. Keep that definition fixed during the test so it is not adjusted afterward to make alerts appear correct.
Time matters too. An alert issued after the fault occurred cannot demonstrate advance warning. An alert with so little usable lead time that the team cannot respond may have a different value from one that supports a planned intervention. Evaluate lead time against actual service arrangements.
Ask how the historical test was constructed
Determine which equipment, operating conditions, dates, and event types were included. A model evaluated on one equipment population may need further evidence for a different application. Similar brand names or sensor lists do not establish equivalent behavior.
Keep information available at the prediction time separate from later knowledge. A final repair code, replacement invoice, or technician note created after the event should not be treated as if the model could have used it beforehand. That would allow the answer to leak into the test.
Also ask how missing records and equipment without an observed event were handled. Excluding difficult cases can make a result look cleaner while changing what the test represents. Have qualified analytics reviewers examine the method rather than relying only on a headline percentage.
Use an alert-to-action record
| Stage | What to retain | Question it answers |
|---|---|---|
| Prediction | Timestamp, model version, equipment, output, and available input state. | What was actually known and claimed at that time? |
| Triage | Qualified interpretation and supported response decision. | What action was appropriate for this alert? |
| Investigation | Relevant findings and their limitations. | Was a condition established, and how? |
| Intervention | Authorized work and timing. | Did the response change the later observation? |
| Outcome | The defined event status and observation period. | What result can the evidence support? |
Do not count every intervention as a prevented failure
If a technician acts after an alert and the equipment later operates normally, the record shows an alert, an intervention, and subsequent observations. It does not by itself prove that a failure would have occurred without the work.
That missing alternative is important. A weak alert followed by unnecessary work can also end with no failure. A suitable evaluation method must distinguish confirmed findings, justified preventive work, uncertain cases, and unsupported causal claims.
Use qualified reviewers to design the pilot and any comparison. Never withhold necessary safety or maintenance action merely to see whether a model was right. Operational and ethical requirements govern the work, and the analysis must account for them.
Evaluate the complete service burden
Include alerts requiring review, missed events, repeated notifications, data outages, investigation time, and work the team cannot act on. A model that finds some useful cases may still create an unsustainable queue without suitable triage.
NIST’s voluntary AI Risk Management Framework supports managing risks across the use of an AI system. For HVAC, the relevant question is how the model, equipment information, qualified judgment, and response process work together.
Bring exact equipment and manufacturer-support questions to Mar-Hy when a pilot requires them. Treat a predictive output as supported information within the service process, with its uncertainty visible, rather than a guaranteed failure forecast.
PROSTOCK AT MAR-HY
PROSTOCK PROFESSIONAL QUALITY HVAC PARTS AND SUPPLIES
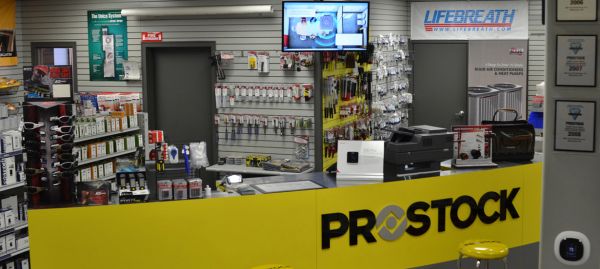
Support for the next service call.
Mar-Hy Distributors adopted the Prostock concept to enhance our support of local HVAC contractors. Since opening our Prostock store, we have received positive feedback from contractors on how they have improved response time to their customers. Our HVAC contractors have been able to stay ahead of the competition with access to our extensive inventory of Prostock Parts.
Quality parts. Contractor support.
Our Prostock replacement parts department is committed to improving the business of our HVAC contractors by providing quality services, competitive pricing, and products and supplies that earn customer trust and build lifetime customer satisfaction. We value our contractors and will continue to provide top of the line service for all of your HVAC needs.
Our team at Mar-Hy Distributors would like to thank you for your business.


